
Enterprise AI Factory: Architecture, Engineering & Operations
Design, build and operate enterprise GPU clusters: GB300 NVL72 and DGX racks, InfiniBand and RoCE fabrics, lossless networking, power and liquid cooling, storage, Base Command Manager provisioning, Kubernetes and Run:ai orchestration, and production troubleshooting, with labs on a live HPC cluster.
Built for the people who run AI infrastructure
Cloud and DevOps engineers
Move from VMs and containers to GPU clusters: RDMA fabrics, schedulers, GPU operators and the failure modes that only show up at scale.
Data centre, systems and network admins
Learn the power, liquid cooling, fabric and provisioning work behind 132 kW racks, InfiniBand and lossless Ethernet.
Platform and AI infrastructure architects
Size a bill of materials, design rail-optimized pods and reason about DGX SuperPOD procurement with confidence.
AI/ML and MLOps engineers
Understand HBM limits, communication patterns and MFU, and see why the fabric decides how fast your training runs.
Also a strong fit if you are preparing for NVIDIA AI infrastructure and networking certifications.
Six outcomes you can prove on a live cluster
Twenty-three modules across four parts: AI and GPU foundations, AI networking and high-speed fabrics, AI cluster and data centre design, and GPU platform operations.
Architect high-density GPU racks
Read the thermal (CDU liquid cooling) and electrical (132 kW) anatomy of GB300 NVL72 and DGX systems, and size a rack bill of materials.
Design AI fabrics
Design rail-optimized 2-tier and 3-tier InfiniBand and RoCE fat-tree fabrics with UFM telemetry and adaptive routing.
Engineer lossless networking
Configure and reason about RDMA, RoCEv2, PFC, ECN and DCQCN so collectives run without drops or deadlocks.
Automate cluster provisioning
Build clusters with NVIDIA Base Command Manager: golden images, OFED, CUDA and DCGM diagnostics with zero drift.
Orchestrate GPUs
Schedule GPU work with Slurm, the GPU Operator, Multus CNI and Run:ai, using fractional GPUs, fair-share queues and preemption.
Accept and operate clusters
Run site surveys, XID triage and multi-node NCCL sweeps for client acceptance and QoS, and tune storage with GPUDirect Storage.
Taught by practising AI consultants
Two consultants who work hands-on with GPU platforms, infrastructure and embedded systems, and mentor you through every lab.
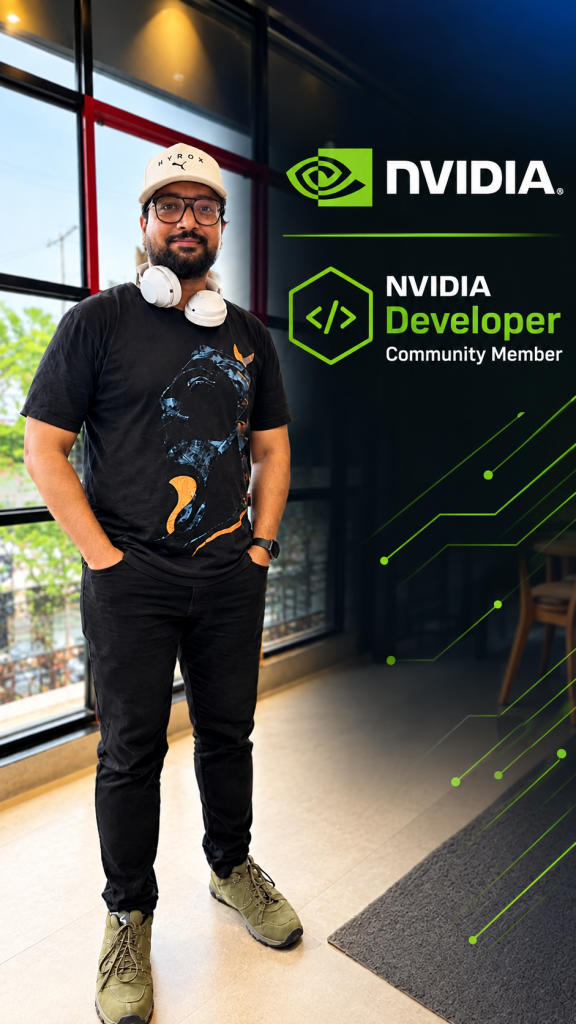
Aravind Kumar TS
14+ years of experience in Infrastructure as services including Cloud Computing, Devops and Cloud Security.
Connect on LinkedIn →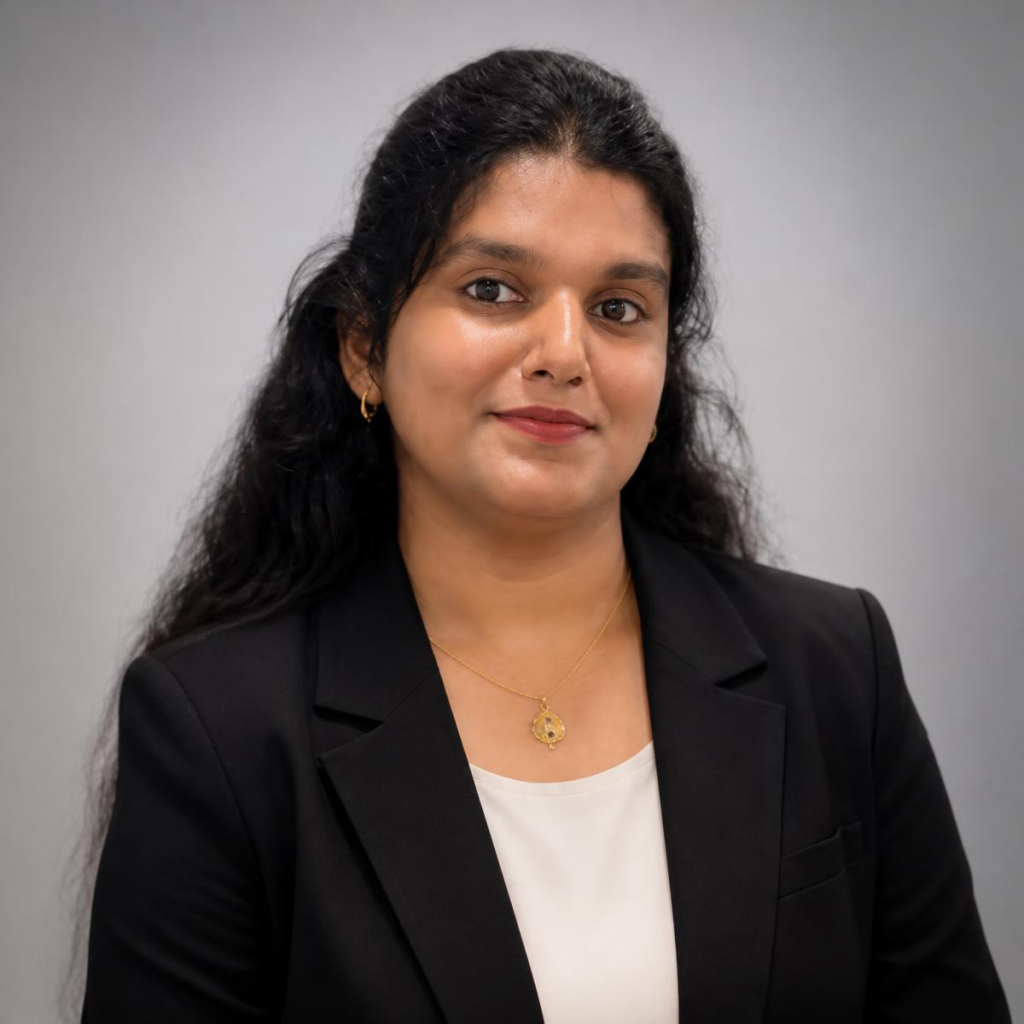
madhu mathy
Passionate about scalable AI infrastructure, high-performance computing, and distributed GPU clusters. Writing about Linux, Cloud, and system architecture.
Connect on LinkedIn →An execution-first program, not just slides
You leave with real cluster experience, a design portfolio and a community, not just a certificate.
Dedicated HPC cluster access
Personal SSH access to a multi-GPU HPC cluster with NVIDIA accelerators, ConnectX SuperNICs and high-speed fabrics, available 24/7.
Recordings, notes and runbooks
Every live session is recorded, and the recordings and notes are available for 9 weeks from the date the course starts, plus a Git repository of runbooks for provisioning, acceptance, cordon, drain and RMA.
Certification question bank
NVIDIA certification question bank and mock exams aligned to NCA-AIIO, NCP-AIN and NCP-AII.
1-on-1 mentorship
Direct mentorship from practising AI consultants, plus resume reviews and architecture interview prep for AI infrastructure roles.
WhatsApp community
An active learner and alumni community on WhatsApp for doubts, design reviews and ongoing networking.
Verifiable certificate
A verifiable CareerByteCode certificate signed by Sangeetha, Director, that you can add to LinkedIn and your resume.
Aligned to three NVIDIA certifications
The syllabus maps to the NVIDIA AI infrastructure and networking certification tracks, and you practise with a question bank and mock exams.
NCA-AIIO (Associate)
AI infrastructure and operations fundamentals. Try the NCA-AIIO practice exam on CareerByteCode.
NCP-AIN (Professional)
AI networking: InfiniBand, Spectrum-X, RoCE and fabric operations. Try the NCP-AIN practice exam.
NCP-AII (Professional)
AI infrastructure: bring-up, provisioning, validation and troubleshooting of GPU clusters, covered by Weekends 7 and 8. Try the NCP-AII practice exam.
CareerByteCode is an independent training program, not affiliated with or endorsed by NVIDIA Corporation. NVIDIA certification exams are booked and paid for separately with NVIDIA.
Eight weekends on a live GPU cluster
- 8 weekends, 16 live sessions of 1.5 hours (Saturday and Sunday, 9:00 PM to 10:30 PM IST)
- 23 modules in 4 parts and 10 hands-on HPC cluster labs
- Dedicated 24/7 SSH access to a multi-GPU HPC cluster
- Session recordings and notes for 9 weeks, plus a Git repository of runbooks
- NVIDIA certification question bank and mock exams
- 1-on-1 mentorship, resume and architecture interview prep
- WhatsApp community and a verifiable CareerByteCode certificate
- Freelancing pathway with 55% to 80% revenue share
Course fee ₹40,000 + 18% GST (₹47,200 all-in). Why it's worth it →
A live, lab-first course on the enterprise AI factory
The Enterprise AI Factory course is a live cohort that runs for eight weekends: 16 sessions of 1.5 hours, every Saturday and Sunday from 9:00 PM to 10:30 PM IST. Twenty-three modules in four parts take you from AI workloads and GPU silicon, through scale-up and scale-out fabrics, lossless networking, power, cooling and storage, to provisioning, orchestration, observability and client acceptance. New batches start regularly because of high demand.
Why a live cluster matters
AI infrastructure is learned at the keyboard. Every learner gets dedicated SSH access to a multi-GPU HPC cluster with NVIDIA accelerators, ConnectX SuperNICs and high-speed fabrics, available 24/7. Around half of the program is CLI work: perftest RDMA benchmarks, NCCL sweeps, device plugins, Slurm scripts and Kubernetes manifests. The rest is a co-designed systems view and troubleshooting drills on injected faults.
Who should join, and what you need
The course is built for cloud and DevOps engineers, data centre, systems and network administrators, platform and AI infrastructure architects, and AI/ML and MLOps engineers. You need the Linux command line, file systems and bash, plus networking fundamentals such as IP, subnets, VLANs, routing and the OSI model. Docker and Kubernetes awareness helps. No prior InfiniBand, AI, deep learning or Python is required.
Fee and format
The course fee is ₹40,000 plus 18% GST, which is ₹47,200 all-in, paid securely through Razorpay. Enrolment includes session recordings and notes for 9 weeks from the course start date, the runbook repository, the NVIDIA certification question bank and mock exams, 1-on-1 mentorship, resume and architecture interview prep, the WhatsApp community and a verifiable certificate signed by Sangeetha, Director.
Common questions
What is the Enterprise AI Factory course, in one line?
How much is the fee?
Who teaches it?
What is the format and timing?
What do I need to know before I join?
Do I get real GPU hardware to practise on?
Does it prepare me for NVIDIA certifications?
What do I walk away with?
Can I earn or freelance after completing this program?
Finish with the CareerByteCode Certified Enterprise AI Factory Engineer credential
Complete the program and earn a verifiable certificate you can add to LinkedIn and your resume. It is built to be recognised fast by recruiters and to give your job search a concrete proof point.
 Verified Credential
Certificate of Completion
This certifies that
Your Namehas successfully completed the program
Enterprise AI Factory: Architecture, Engineering & Operations
CareerByteCode Certified Enterprise AI Factory Engineer Sangeetha
Director, CareerByteCode
Credential ID
CBC-AIFACTORY-2026-0001
Sample certificate. Every graduate receives one with their own name and a unique verifiable ID. Each certificate is valid for 12 months from its issue date.
-
Verifiable in seconds
Each certificate carries a unique ID and a public verify link, so a recruiter can confirm it is real without contacting you.
-
Add it to your LinkedIn
It drops straight into your Licenses and Certifications section using the issuer name, issue date, and credential ID.
-
Proof you can do the work
It is awarded for completing hands-on cluster labs, design work and troubleshooting drills, so it signals applied AI infrastructure skill to hiring teams.
-
Speaks the recruiter's language
A clear, role-titled credential that matches the terms hiring teams and ATS filters actually search for, helping you move faster through screening.
Every certificate is verifiable. Check any credential ID at careerbytecode.in/verify.
What you walk away with, and where you grow
Eight weekends in, you can size, build, run and troubleshoot a GPU cluster, with a design portfolio and runbooks to prove it. Then you keep growing through our community and freelancing network.
Real cluster experience
Hours of keyboard-level work on a live multi-GPU HPC cluster: RDMA benchmarks, NCCL sweeps, Slurm and Kubernetes scheduling, and injected-fault drills.
A design portfolio
An NVL72 rack bill of materials, a 32-node rail-optimized fabric design, a UFM telemetry review and a site survey you can walk an interviewer through.
Runbooks you keep
Session recordings and notes for 9 weeks from the course start date, plus a Git repository of runbooks for cordon, drain, RMA and acceptance testing, ready for your first production cluster.
Grow through our community
Join a global community of engineers. Showcase your work, stay visible to recruiters, and speed up the opportunities that come your way.
Earn through freelancing
Turn your AI infrastructure skills into income. Strong candidates are invited into our freelancing programs to get paid for real work.
Ready to build the AI factory?
Join the next weekend cohort, get your own seat on a live GPU cluster, and leave able to run it in production.
What our learners say
Loading reviews...
Write a review
Reviews are open to graduates of this course. Verify yourself with the email you enrolled with, or your credential ID. Every review is checked before it appears.