
Firestore Hands-On: A NoSQL Database for Apps
What you build: a to-do app on Firestore in the free tier, in your own Google Cloud account. Every step, command and screenshot explained for beginners.

✍️ Translate this blog into Hindi, Tamil or Telugu
In this lab you create a Firestore database and build a small to-do app in Python that adds, lists, updates, queries and deletes tasks. The app talks to Firestore's REST API with your own login token, so it needs no extra packages and no key file. You also meet the most common Firestore surprise: a query that needs an index. You create the index, run the query again, and finish by deleting the whole database.
Who it is for: beginners who know a little Python and have only used SQL tables (or no database at all). Time: about 1 hour. Cost: free tier (Firestore gives 1 GiB of storage and 50,000 reads, 20,000 writes and 20,000 deletes per day free; this lab uses a few dozen).
Every command below was run for real by the CareerByteCode Team on a fresh Google Cloud project, and every output and screenshot is the real result we got. We ran the commands from a terminal with the Google Cloud CLI and Python 3; Cloud Shell in your browser has both, so you can copy and paste each command there.
⭐ Recommended by CareerByteCode · BytePlay courseNVIDIA GPU AI Factory: Architecture, Engineering & Operations₹40,000Start learning →Part A: Firestore in plain English
Firestore is a NoSQL document database. Instead of tables with fixed columns, it stores documents: small records with named fields, a bit like JSON. Documents live in collections. Google runs the servers, copies your data and scales it; you only read and write.

The words you need:
- Database: here the one called
(default), in Native mode (the mode for new apps), in the regionus-east1. - Collection: a group of documents, here
tasks. You do not create it; it appears when you add the first document. - Document: one record with an id (Firestore can make one for you) and fields with types: string, integer, boolean, timestamp and more.
- Index: a sorted list that makes a query fast. Firestore makes a single-field index for every field by itself. A query that filters on one field and sorts on another needs a composite index, which you create once.
- Query: a question like "tasks where done is false, highest priority first".
Real-life example: a school register. Each student card (document) sits in a class box (collection). To answer "present students, sorted by roll number" quickly, the school keeps a ready-made list for exactly that question (the composite index).
SQL vs Firestore in one line: in SQL you design tables first and join them in queries; in Firestore you store each document the way your app reads it, and every query must be answerable from an index.
Before you start
- A Google Cloud account (the free trial works) and a project with billing linked. A project can have one free
(default)database. - Open Cloud Shell (the
>_icon at the top of the Google Cloud console). It hasgcloudandpython3. - Save your project id (put your own id between the quotes):
export PROJECT_ID="your-project-id"- Run all steps in the same folder (for example your home folder).
Part B: the lab
Step 1: turn on Firestore and create the database
Why: --type=firestore-native picks Native mode; --location cannot be changed later, so choose the region near your users.
gcloud config set project $PROJECT_ID
gcloud services enable firestore.googleapis.com
gcloud firestore databases create --location=us-east1 --type=firestore-native 2>&1 | tail -3
Updated property [core/project].
uid: 242f5504-ca0d-483b-a2ec-f06b3bac4b6e
updateTime: '2026-11-17T22:48:49.408148Z'
versionRetentionPeriod: 3600sStep 2: check the database
gcloud firestore databases describe --database="(default)" --format="yaml(name.basename(),locationId,type,concurrencyMode)"concurrencyMode: PESSIMISTIC
locationId: us-east1
name: (default)
type: FIRESTORE_NATIVE
Step 3: write the to-do app
Why: one small Python file, standard library only. Read it top to bottom:
BASEis the address of your database's documents in the Firestore REST API.call()sends a request with your token in theAuthorizationheader and prints Firestore's error message if something goes wrong.- Each field is sent with its type:
{"stringValue": ...},{"integerValue": ...},{"booleanValue": ...}. addcreates a document intasks(Firestore picks the id).listreads all documents.donechanges one field only (updateMask).openruns a query.deleteremoves a document.
cat > todo.py <<EOF
import json, os, sys, urllib.request, urllib.error

BASE = "https://firestore.googleapis.com/v1/projects/" + os.environ["PROJECT_ID"] + "/databases/(default)/documents"

def call(method, url, body=None):
    req = urllib.request.Request(url, method=method, data=json.dumps(body).encode() if body is not None else None)
    req.add_header("Authorization", "Bearer " + os.environ["TOKEN"])
    req.add_header("Content-Type", "application/json")
    try:
        with urllib.request.urlopen(req) as r:
            return json.loads(r.read() or b"{}")
    except urllib.error.HTTPError as e:
        err = json.loads(e.read())
        err = err[0] if isinstance(err, list) else err
        print("ERROR", e.code, err["error"]["message"][:300]); sys.exit(1)

def show(doc):
    f = doc["fields"]
    print(doc["name"].split("/")[-1], "|", f["title"]["stringValue"], "| priority", f["priority"]["integerValue"], "| done" if f["done"]["booleanValue"] else "| open")

cmd = sys.argv[1]
if cmd == "add":
    doc = call("POST", BASE + "/tasks", {"fields": {"title": {"stringValue": sys.argv[2]},
               "priority": {"integerValue": sys.argv[3]}, "done": {"booleanValue": False}}})
    print("added:", end=" "); show(doc)
elif cmd == "list":
    for doc in call("GET", BASE + "/tasks").get("documents", []): show(doc)
elif cmd == "done":
    show(call("PATCH", BASE + "/tasks/" + sys.argv[2] + "?updateMask.fieldPaths=done", {"fields": {"done": {"booleanValue": True}}}))
elif cmd == "open":
    query = {"structuredQuery": {"from": [{"collectionId": "tasks"}],
             "where": {"fieldFilter": {"field": {"fieldPath": "done"}, "op": "EQUAL", "value": {"booleanValue": False}}},
             "orderBy": [{"field": {"fieldPath": "priority"}, "direction": "DESCENDING"}]}}
    for row in call("POST", BASE + ":runQuery", query):
        if "document" in row: show(row["document"])
elif cmd == "delete":
    call("DELETE", BASE + "/tasks/" + sys.argv[2]); print("deleted", sys.argv[2])
EOF
python3 -c "import ast; ast.parse(open(\"todo.py\").read()); print(\"todo.py OK\")"
todo.py OK
Step 4: add three tasks
Why: gcloud auth print-access-token gives a short-lived token for your own account; the app reads it from TOKEN. Tokens expire after about an hour, so each step gets a fresh one.
export TOKEN=$(gcloud auth print-access-token)
python3 todo.py add "Finish the Firestore lab" 3
python3 todo.py add "Read the IAM post" 2
python3 todo.py add "Share the lab with a friend" 1
added: 4eJUojED4La77JQiCngD | Finish the Firestore lab | priority 3 | open
added: 5d0bey99266WbOIEovPh | Read the IAM post | priority 2 | open
added: oLQrqyZIJAAF9K2jbpTB | Share the lab with a friend | priority 1 | openStep 5: list every task
export TOKEN=$(gcloud auth print-access-token)
python3 todo.py list
4eJUojED4La77JQiCngD | Finish the Firestore lab | priority 3 | open
5d0bey99266WbOIEovPh | Read the IAM post | priority 2 | open
oLQrqyZIJAAF9K2jbpTB | Share the lab with a friend | priority 1 | open
Step 6: mark one task done
Why: the PATCH with updateMask.fieldPaths=done changes only done and leaves the other fields as they are. The command finds the id of the "IAM post" task first, so you do not need to copy ids by hand.
export TOKEN=$(gcloud auth print-access-token)
ID=$(python3 todo.py list | grep "IAM post" | cut -d" " -f1)
python3 todo.py done $ID
5d0bey99266WbOIEovPh | Read the IAM post | priority 2 | done
Break it: a query that needs an index
Ask for open tasks, highest priority first. This filters on done and sorts on priority:
export TOKEN=$(gcloud auth print-access-token)
python3 todo.py open
ERROR 400 The query requires an index. You can create it here: https://console.firebase.google.com/v1/r/project/your-project-id/firestore/indexes?create_composite=ENCODED_INDEX_ID
This is not a bug in your code. Firestore never scans a whole collection; every query must use an index. Single-field indexes exist already, but "filter on one field + sort on another" needs a composite index. The error even gives a console link that fills the form in for you.
Fix it: create the composite index
🧪⭐ Recommended by CareerByteCode · ByteLabs project bundleCloud and DevOps Realtime Starter₹499Build the projects →You can click the link in the error, or create the same index with one command: done ascending and priority descending, for the collection tasks.
gcloud firestore indexes composite create --collection-group=tasks \
  --field-config=field-path=done,order=ascending \
  --field-config=field-path=priority,order=descending 2>&1 | tail -2
gcloud firestore indexes composite list --format="table(name.basename(),state,fields[0].fieldPath,fields[1].fieldPath)"
..........done.
Created index [CICAgOjXh4EK].
NAME STATE FIELD_PATH FIELDS_FIELD_PATH
CICAgOjXh4EK READY done priority
Building an index takes a few minutes (ours took about 7). Wait for READY.
POC: the query works
export TOKEN=$(gcloud auth print-access-token)
python3 todo.py open
4eJUojED4La77JQiCngD | Finish the Firestore lab | priority 3 | open
oLQrqyZIJAAF9K2jbpTB | Share the lab with a friend | priority 1 | open
Proof: only open tasks are listed, and priority 3 comes before priority 1. The task marked done is not in the list.
Delete a finished task
export TOKEN=$(gcloud auth print-access-token)
ID=$(python3 todo.py list | grep "| done" | cut -d" " -f1)
python3 todo.py delete $ID
python3 todo.py listdeleted 5d0bey99266WbOIEovPh
4eJUojED4La77JQiCngD | Finish the Firestore lab | priority 3 | open
oLQrqyZIJAAF9K2jbpTB | Share the lab with a friend | priority 1 | open
Clean up (delete everything)
Why: deleting the database removes every collection, document and index in it. You can create a new (default) database later.
gcloud firestore indexes composite delete $(gcloud firestore indexes composite list --format="value(name)") --quiet 2>&1 | tail -1
gcloud firestore databases delete --database="(default)" --quiet 2>&1 | tail -2
echo "databases left: $(gcloud firestore databases list --format="value(name)" | wc -l)"
Deleted composite index [CICAgJiUpoMK].
updateTime: '2026-11-17T22:48:49.408148Z'
versionRetentionPeriod: 3600s
databases left: 0
FAQ
Do I need the Firebase console? No. Firestore is part of Google Cloud; gcloud and the REST API are enough. Firebase adds mobile and web SDKs and security rules for apps that talk to Firestore directly from a phone or browser.
Why not the google-cloud-firestore Python library? It is the usual choice in real apps and it is great. We used the REST API so the lab needs no installs and you can see exactly what goes over the wire. In Cloud Shell, pip install google-cloud-firestore and the library uses your login automatically.
What is Native mode vs Datastore mode? Native mode is Firestore with real-time updates and the document model; Datastore mode keeps compatibility with the older Datastore API. Pick Native for new apps.
How do I avoid surprise indexes in production? Run each new query once in a test project, create the indexes it asks for, and keep them in a file (firestore.indexes.json in Firebase projects).
Is my data safe if a server fails? Yes. Firestore keeps copies across zones in the region (or across regions with a multi-region location).
How big can a document be? Up to 1 MiB. Keep documents small and put big files in Cloud Storage.
Troubleshooting
| You see | Why | Fix |
|---|---|---|
The query requires an index | Filter on one field + sort on another | Create the composite index (Fix it step), wait for READY |
ALREADY_EXISTS: index already exists | You created it before, or an old one is still being deleted | List the indexes; wait a few minutes after a delete |
ERROR 401 | The token expired (about 1 hour) | Run export TOKEN=$(gcloud auth print-access-token) again |
ERROR 404 on every call | The database was not created or was deleted | Run Step 1 |
ERROR 403 | Your account has no Firestore role in this project | Ask for the Cloud Datastore User role |
KeyError: PROJECT_ID | The variable is not set in this terminal | export PROJECT_ID="your-project-id" |
What next
- Query big data with SQL instead: "BigQuery for Beginners: Query Billions of Rows for Free", in this series on ByteBlog.
- Our tested Kubernetes lab: Zero to Kubernetes in 2.5 hours.
- More hands-on posts on ByteBlog, guided projects in ByteLabs and the full courses.
Prepared by the CareerByteCode Team from our tested lab, with AI help for the write-up.
⭐ Keep learning with CareerByteCode
Hand-picked to go deeper on this topicGet CareerByteCode Team's next blog by email
One email a week when they publish. Add the weekly Best of ByteBlog too. No spam, unsubscribe with one click.
We email you once to confirm. By subscribing you agree to the privacy policy.
More from CareerByteCode Team
 CareerByteCode Team
Cloud Storage Deep Dive: Classes, Lifecycle and Signed URLs
What you build: a private bucket with storage classes, a lifecycle policy, object versions and expiring signed URLs, in your own Google Cloud account. Every step tested.
#beginners CareerByteCode Team
BigQuery for Beginners: Query Billions of Rows for Free
What you build: SQL on a public dataset with millions of rows, then your own sales table with a view and a daily partition, in your own Google Cloud account. Every step tested.
#bigquery CareerByteCode Team
BigQuery ML: Train a Model with Just SQL
What you build: a churn prediction model written in SQL with BigQuery ML, scored and used for predictions, in your own Google Cloud account. Every step tested.
#beginners CareerByteCode Team
Cloud Logging Hands-On: Find Any Error in Seconds
What you build: log queries, log-based metrics and sinks, in your own Google Cloud account. Every step, command and screenshot explained for beginners.
Readers of this blog also read
 CareerByteCode Team
This week at CareerByteCode: 2 to 8 Nov 2026
Here is what happened at CareerByteCode this week, from 2 Nov 2026 to 8 Nov 2026. CareerByteCode is a free community for influencers and content creators in...
 Srilakshmi TFreelancer
SRE in Practice | Day 2: SRE vs DevOps
Two complementary perspectives on delivering and running reliable software. Concept, production example, and a hands-on release-mapping lab.
 Madhumathy UFreelancer
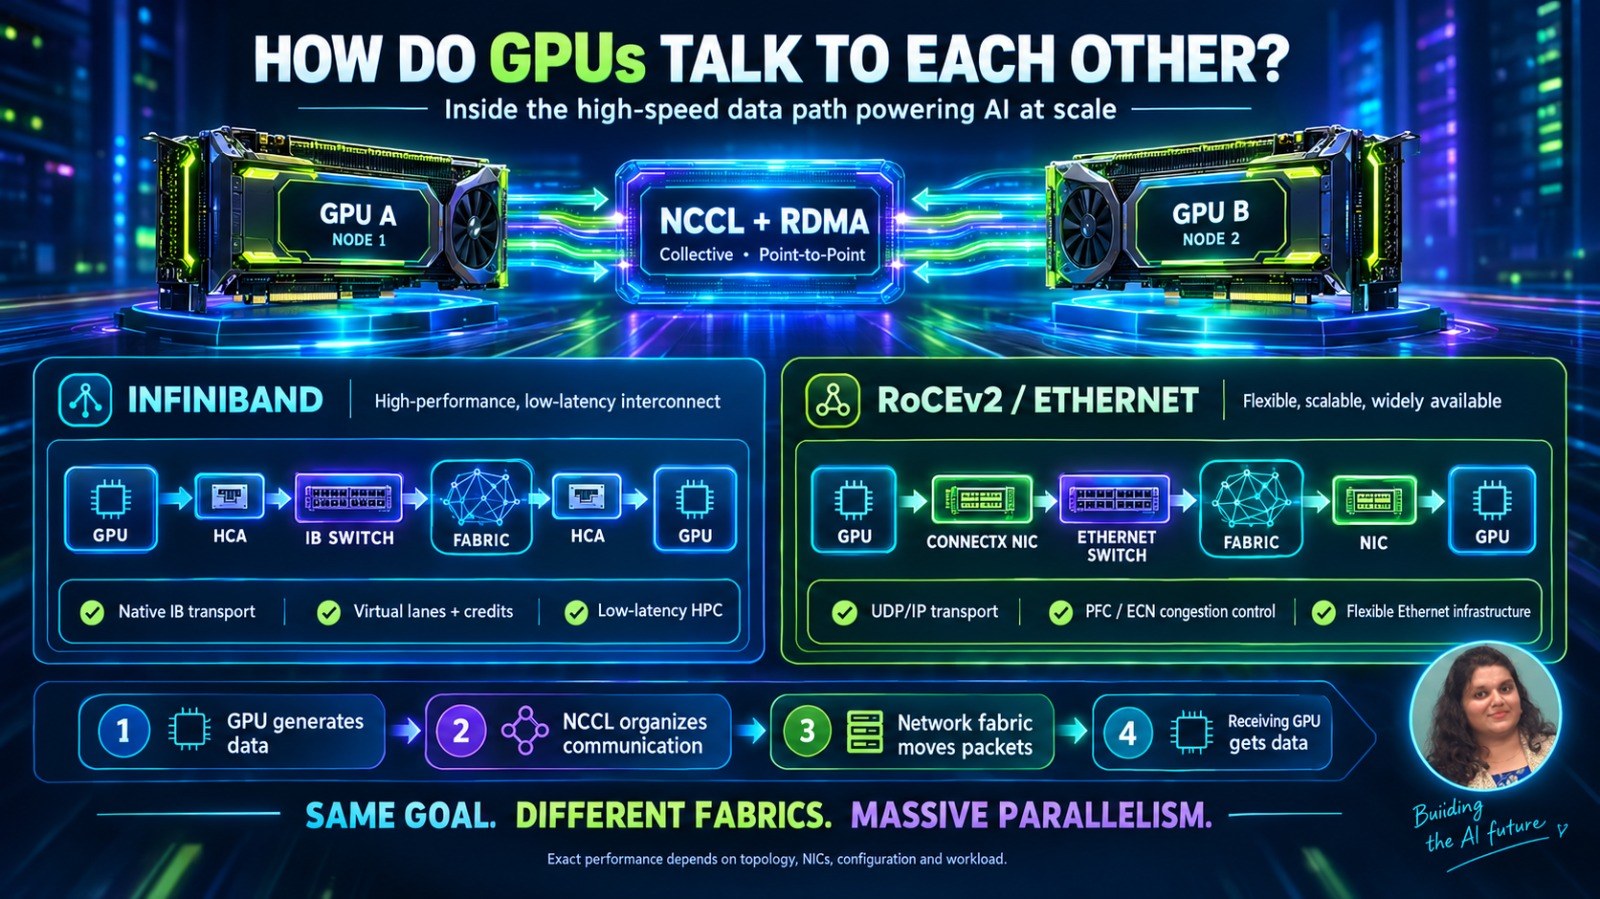
🚀 How Do GPUs Actually Talk to Each Other? The Hidden Network Powering AI at Scale
Your GPU may be incredibly powerful. But what happens when one GPU needs to communicate with hundreds of others?
 Srilakshmi TFreelancer
The Midnight Cloud Bill: How Terraform Saved Us Lakhs by Destroying Dev Environments Every Night
By Srilakshmi Thulasiraman | Cloud Infrastructure Automation
💬 Comments (0)
Top · NewestSign in to comment